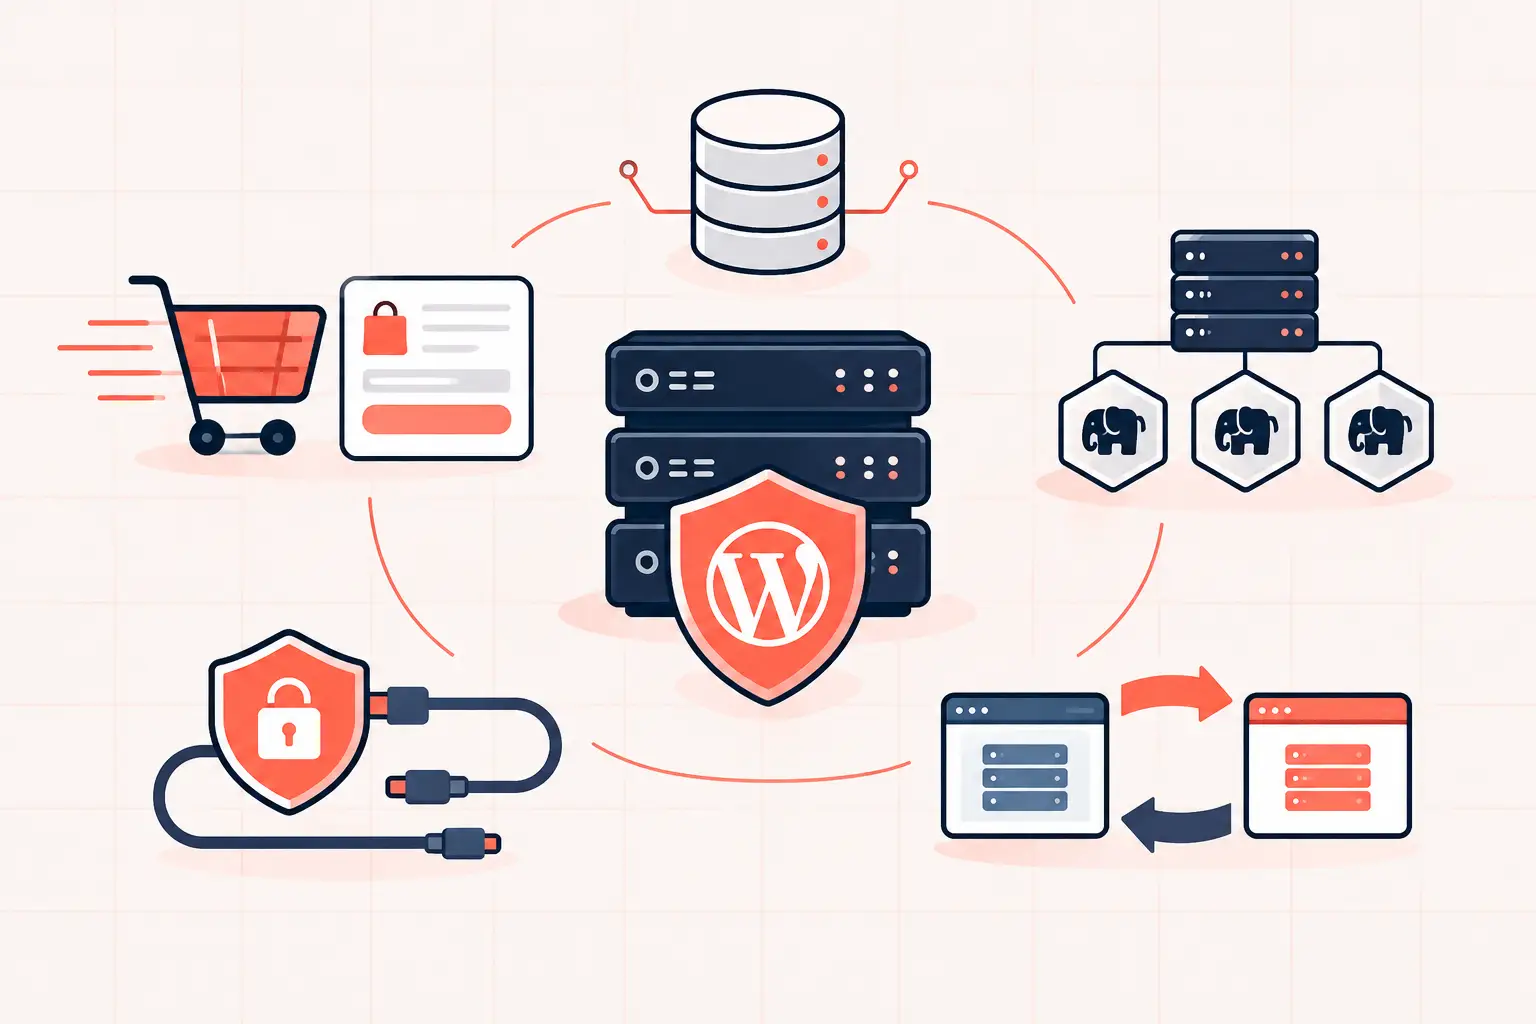
A backup is not WordPress disaster recovery planning. It is only one dependency. Recovery works when you can restore the right files and database, verify the site safely, and put traffic back on it within a defined window. If nobody knows which backup is clean, where DNS is managed, or how to test checkout after a restore, you have backup storage, not a recovery plan.
For most WordPress sites, the practical target is simple: keep recoverable copies off the production server, document the restore sequence, and test it before an outage forces the issue. WooCommerce stores and membership sites need tighter recovery objectives because orders, accounts, and payments change constantly.
Start WordPress disaster recovery planning with RPO and RTO
Two numbers determine how much protection your site actually needs. Your recovery point objective, or RPO, is the maximum acceptable data loss. Your recovery time objective, or RTO, is the maximum acceptable downtime.
A brochure site that changes weekly may accept a 24-hour RPO and a four-hour RTO. A WooCommerce store taking orders every minute cannot. If its latest usable database backup is six hours old, restoring it may remove paid orders, customer accounts, inventory changes, and support tickets. That is an operations problem, not a WordPress problem.
Set targets based on the cost of being wrong:
| Site type | Sensible starting RPO | Sensible starting RTO |
|---|---|---|
| Low-change marketing site | 24 hours | 4-8 hours |
| Content publisher | 4-24 hours | 2-4 hours |
| WooCommerce store | 1 hour or less | 1-2 hours |
| Membership or LMS site | 1 hour or less | 1-2 hours |
These are starting points, not universal rules. A high-volume store may need transaction-aware backups, payment-provider reconciliation, and a tested process to recreate orders after the last database snapshot. No ordinary WordPress backup can capture every external payment event automatically.
What a recoverable WordPress backup must contain
A usable restore point needs more than `wp-content/uploads`. At minimum, preserve the database, WordPress files, plugins, themes, uploads, and the configuration needed to connect everything back together.
The database contains posts, settings, users, WooCommerce orders, and plugin data. The filesystem holds media, custom code, plugins, themes, cache configuration, and sometimes deployment artifacts. Restoring one without the other can produce missing images, fatal errors from mismatched plugin versions, or an apparently working site with broken checkout logic.
Keep copies of these items outside the web server:
- A consistent database dump or snapshot
- The full `wp-content` directory, including uploads and any must-use plugins
- `wp-config.php`, with secrets stored securely and separately if policy requires it
- Web server configuration, redirect rules, cron configuration, and SSL or DNS records where relevant
- A record of PHP version, extensions, object cache settings, and scheduled jobs
Do not treat a backup plugin's green checkmark as proof of recoverability. It may confirm that an archive was created, not that the archive is complete, uncorrupted, accessible, and restorable on a clean server.
Use layered backups, not one backup job
A sound setup normally combines frequent database backups with less frequent filesystem backups, plus provider-level snapshots where available. Each layer covers a different failure mode.
For example, hourly database backups protect recent orders. Daily file backups cover media and code changes. Offsite copies protect against server loss or account-level mistakes. Immutable or versioned storage provides a better defense against ransomware and an attacker deleting the same backups they found in your hosting account.
Snapshots are useful for fast rollback, but they are not automatically a complete disaster recovery system. A snapshot stored in the same account, region, or compromised control panel may disappear with the production environment. Follow the 3-2-1 principle in practical terms: keep multiple copies, on different storage systems, with at least one copy outside your primary environment.
Write the runbook before the outage
When a site is down, people make destructive decisions quickly. A short runbook turns a chaotic incident into a sequence of checks. Store it somewhere available when WordPress, email on the same domain, or the hosting dashboard is unavailable.
Your runbook should name the recovery owner and backup owner, list emergency credentials and where they are stored, identify domain and DNS access, and state the RPO and RTO. It should also include the exact restore procedure for your platform, not a vague instruction to “restore backup.”
Document the decision points. If the site is slow because PHP workers are saturated or a database query is bloated, restoring a backup will not fix it. If a plugin update caused a fatal error, disabling or rolling back that plugin may be safer than restoring an entire day-old database. If malware is present, restoring blindly can reintroduce the infection if the backup predates neither the compromise nor the vulnerable component.
Define an incident sequence
A practical recovery sequence usually looks like this:
- Confirm the failure scope. Check the public site, wp-admin, server logs, database connectivity, and an external uptime monitor.
- Contain the damage. Put a compromised or unstable site behind maintenance mode, restrict admin access, and preserve logs before making major changes.
- Choose the recovery point. Select the newest backup from before the failure or compromise, not merely the newest available backup.
- Restore into staging or an isolated recovery environment first when time permits.
- Validate critical paths, then switch production traffic only after the site is safe and functional.
For a severe outage, speed matters. But a fifteen-minute validation step can prevent you from publishing a restored site with a broken payment gateway, stale DNS, or a database whose URLs still point to the staging domain.
Test restores the way customers use the site
A restore test is the part most teams skip, and it is the only part that proves the plan. Schedule it at least twice a year. Test more often after changing hosts, moving domains, replacing backup tools, adding a major WooCommerce extension, or changing your deployment process.
Restore to a staging environment that is isolated from production email, payment processing, and search indexing. Do not let a test environment send order emails to customers or charge a live card. Use a staging payment mode and block outbound transactional email unless you are deliberately testing it.
After restoring, check more than the homepage. Confirm that wp-admin loads, users can log in, media files appear, forms deliver to the expected destination, scheduled tasks run, and caches can be purged. For WooCommerce, test product pages, cart updates, coupons, checkout, order creation, stock reduction, and transactional emails.
If you use WP-CLI, record the commands used during the test. A basic database import might look like this:
wp maintenance-mode activate wp db import /secure-backups/site.sql wp search-replace 'https://staging.example.com' 'https://example.com' --skip-columns=guid --dry-run wp cache flush wp rewrite flush --hardDo not run a search-replace against production casually. The command above is an example, and domain handling depends on whether the site uses a separate staging database, serialized data, multisite, or hard-coded URLs. Run a dry run first and keep the original database dump untouched.
Plan for the failures backups do not solve
Recovery planning must account for dependencies outside WordPress. Your domain registrar, DNS provider, CDN, email service, payment gateway, object cache, and third-party APIs can all keep the site broken after a perfect restore.
Maintain a dependency inventory with account owners, escalation contacts, and current configuration details. If Cloudflare or another CDN sits in front of the site, know how to bypass cache during validation and how to purge it after recovery. If Redis is used for object caching, know whether to flush it after a database rollback so stale objects do not conflict with restored data.
For performance incidents, capture baseline metrics before disaster strikes. Record normal TTFB, PHP worker usage, database response time, disk capacity, and error rates. Without a baseline, teams often mistake a resource exhaustion event for a corrupted WordPress install. High-frequency CPU capacity helps with traffic spikes, but it does not replace enough PHP workers, database tuning, or a recovery plan.
Keep the plan current as the site changes
Every major plugin, payment integration, deployment change, and infrastructure migration can alter your recovery procedure. Update the runbook as part of the change process, not after the next incident.
Managed environments with hourly backups, isolated staging, and server-level caching reduce recovery friction. At WP Tango, that operational backstop is built around frequent recovery points and modern high-frequency infrastructure, but the underlying rule applies anywhere: a backup strategy is only credible when the restore has been practiced.
The next time you deploy a risky update, do not ask whether a backup exists. Ask who can restore it, how long it will take, what data will be lost, and how you will prove the recovered site can accept a real customer order.